Portfolio

Hands-on data engineering projects, running on my own Kubernetes lakehouse. More at tigor.nl.

Sovereign, open source

Everything here runs on open-source software (Kafka, Spark, Delta Lake, ClickHouse, Airflow, dbt, Superset, Trino) on Kubernetes in a European cloud region in Amsterdam.

Data sits in open formats (Delta Lake, Parquet) on S3-compatible storage: no vendor lock-in, no licence fees, and you decide where your data lives, which matters for GDPR and strategic independence. The patterns match Databricks and Microsoft Fabric, so skills and designs carry over both ways.

Leveraging AI

I build with an AI coding assistant as a pair engineer: it writes code, deploys and debugs, while I set the direction, review and decide. One engineer can now build in days what used to take a team weeks.

The intention is to run and maintain the platform with AI as much as possible, in a responsible way: humans approve risky changes, secrets stay out of reach, and every change is reviewable in git.

Open source is what makes this work. AI can read the source code, documentation and logs of every component, and the whole platform is described as code (Helm, YAML, SQL). That helps enormously in managing the complexity of a stack this size, where a closed product would be a black box.

Projects

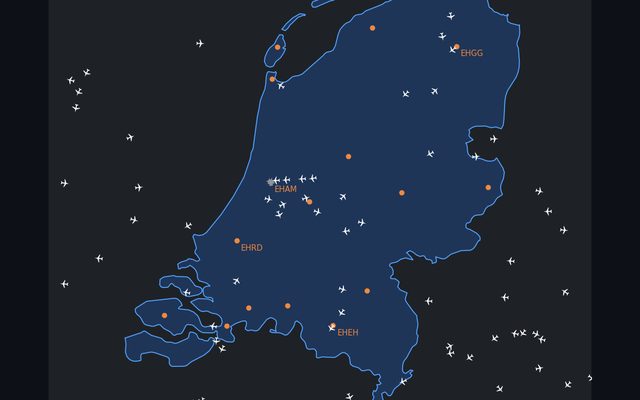
Live map of aircraft over the Netherlands LIVE

Spark Structured Streaming and the ClickHouse Kafka engine

Live aircraft and landings over the Netherlands: Kafka, streaming into ClickHouse and Delta, shown in a real-time report.
KafkaSpark Structured StreamingClickHouseSuperset
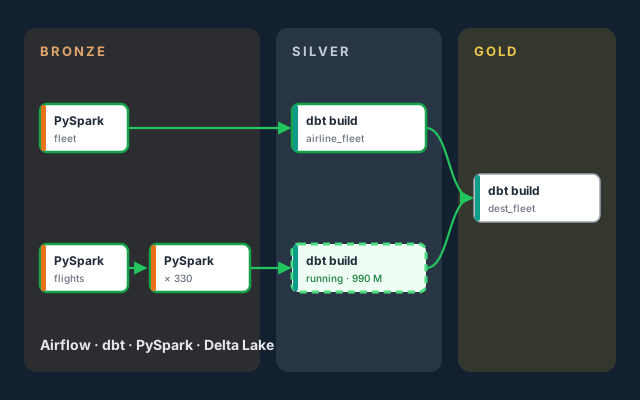
Airflow DAG with bronze, silver and gold layers

Medallion lakehouse with Airflow, dbt and PySpark

Bronze, silver and gold Delta tables: PySpark loads, dbt transforms and tests, Airflow orchestrates. Includes a replay of a 990-million-row run.

AirflowdbtPySparkDelta LakeMedallion